There is no shortage of articles claiming that machine learning will replace human traders. The reality is far more nuanced — and far more interesting. ML does not replace human insight; it amplifies it. The best quantitative traders today are those who understand which ML models are suited to which market problems, how to feed them the right data, and crucially, when to distrust their output.
At StockHunt, our ML stack spans half a dozen model families, each deployed for a specific sub-problem within our trading pipeline. What follows is a frank, practitioner-level guide to how we think about ML in live crypto markets — not the textbook version, but the one forged by real losses and hard-won wins.
Why Crypto Is a Unique ML Problem
Most ML research in finance focuses on equity markets — decades of clean, well-structured data with defined trading hours. Crypto is different. Markets run 24/7 with no circuit breakers. Data quality is highly variable across venues. The asset class is young, meaning historical datasets are small by ML standards. And crucially, the market structure changes rapidly — what worked in 2021 may be actively harmful in 2024.
These characteristics demand a different approach than simply importing a Kaggle notebook and pointing it at Bitcoin price data. You need models that are robust to non-stationarity, that handle missing data gracefully, and that can signal when they are operating outside their training distribution.
The Model Hierarchy: What We Use and Why
1. Gradient Boosting (XGBoost / LightGBM) — Our Workhorses
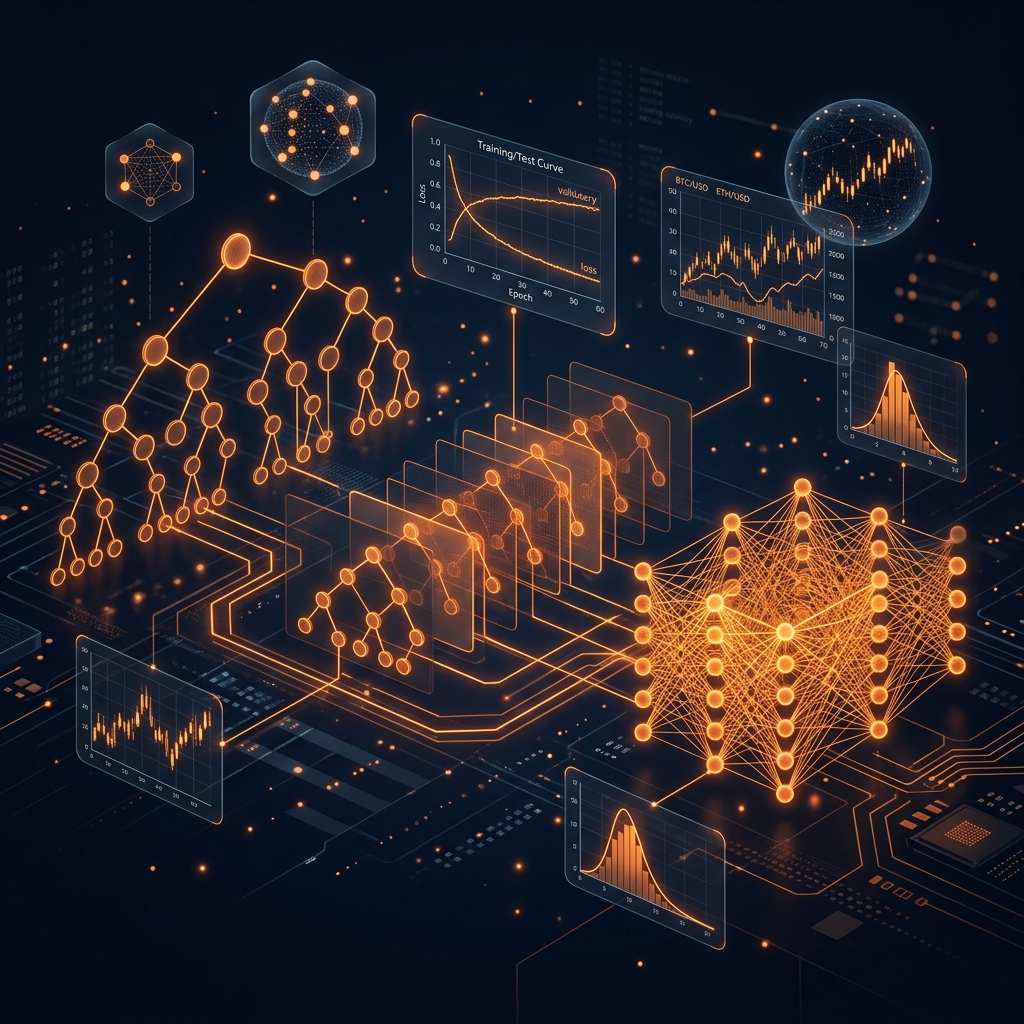
Gradient boosted decision trees remain the single most reliable model family for tabular financial data. They handle mixed feature types naturally, require minimal preprocessing, are robust to outliers (critical in crypto where 10-sigma events occur regularly), and produce well-calibrated probability estimates when tuned correctly.
Our primary signal model is an ensemble of LightGBM models trained on a rolling window of order book features, funding rate derivatives, and on-chain flow metrics. The ensemble approach — training multiple models on overlapping but non-identical feature sets and averaging their predictions — significantly reduces variance and prevents any single correlated feature set from dominating the signal.
2. LSTM Networks — For Sequence-Dependent Patterns
Long Short-Term Memory (LSTM) networks are a type of recurrent neural network designed to learn patterns across variable-length time sequences. In trading, this is useful for problems where the history of how you arrived at the current state matters — for example, detecting building momentum in funding rates or identifying the early signature of a liquidation cascade before it becomes obvious on the price chart.
We use LSTM models specifically for our funding rate anomaly detector and our open interest momentum signal. The key insight from our research: LSTMs outperform gradient boosting when the predictive signal lives in the temporal pattern of features rather than their instantaneous values. For static snapshot predictions, gradient boosting wins almost every time on crypto data.
3. Random Forests — For Regime Classification
Random forests are our preferred model for regime classification tasks — determining whether the market is currently in a trending, mean-reverting, or high-volatility regime. Their interpretability advantage over deep models is significant here: when a regime classifier switches the primary signal model, we want to understand which features drove that switch. With a random forest, feature importance is a first-class output.
Feature Engineering: Where Real Edge Lives
The single biggest mistake made by newcomers to ML trading is spending 90% of their effort on model architecture and 10% on features. In our experience, the opposite ratio produces better results. A simple logistic regression trained on highly engineered features will consistently beat a sophisticated deep learning model trained on raw OHLCV data.
- Order book imbalance ratio: (bid depth - ask depth) / (bid depth + ask depth) at multiple price levels — one of the strongest short-term directional features we have found.
- Funding rate momentum: rate of change of funding rate over 1h, 4h, and 8h windows, capturing building pressure that precedes directional moves.
- Liquidation density: volume of liquidations occurring within defined price bands above and below current price, extracted from exchange liquidation feeds.
- Cross-venue basis: price differential between spot and perpetual across multiple exchanges, a signal of institutional hedging flow.
- On-chain net flow: net BTC/ETH flows into exchanges over rolling windows, a reliable medium-term directional indicator.
The Overfitting Trap and How to Avoid It
Overfitting is the defining challenge of ML in finance. A model that memorises historical patterns without generalising will appear exceptional in backtests and fail immediately in live trading. The crypto market, with its structural shifts and regime changes, is particularly unforgiving of overfit models.
“If your backtest looks too good, it almost certainly is. A Sharpe ratio above 3 on historical crypto data is a red flag, not a celebration.”
We counter overfitting through four mechanisms: strict train/validation/test splits with temporal ordering preserved (never shuffle time-series data), cross-validation using expanding or rolling windows that mimic live deployment conditions, aggressive regularisation in all models (L1/L2, dropout, early stopping), and feature importance pruning — ruthlessly removing features that add complexity without contributing predictive power.
Deploying ML Models in Production
A model that works in a Jupyter notebook and a model that works in live trading are different beasts. In production, you face latency constraints (inference must complete within your signal generation budget), data pipeline reliability (missing or delayed features must be handled gracefully), and model staleness (the market evolves and models must be retrained continuously).
Our production ML pipeline runs model inference on dedicated GPU instances co-located with our order management system. Models are containerised and versioned, with automated shadow deployment — every new model version runs in parallel with the live model, and its predictions are logged and compared before it is promoted to production. We never deploy a model cold into live trading.
The best ML trading edge is not in model complexity — it is in data quality, disciplined feature engineering, and rigorous validation. Build simple models on rich features before reaching for neural networks.